Agent Orchestration
Event-driven orchestration for 100K+ agent sessions: risk-based routing, cost-aware models, and multi-region resilience.
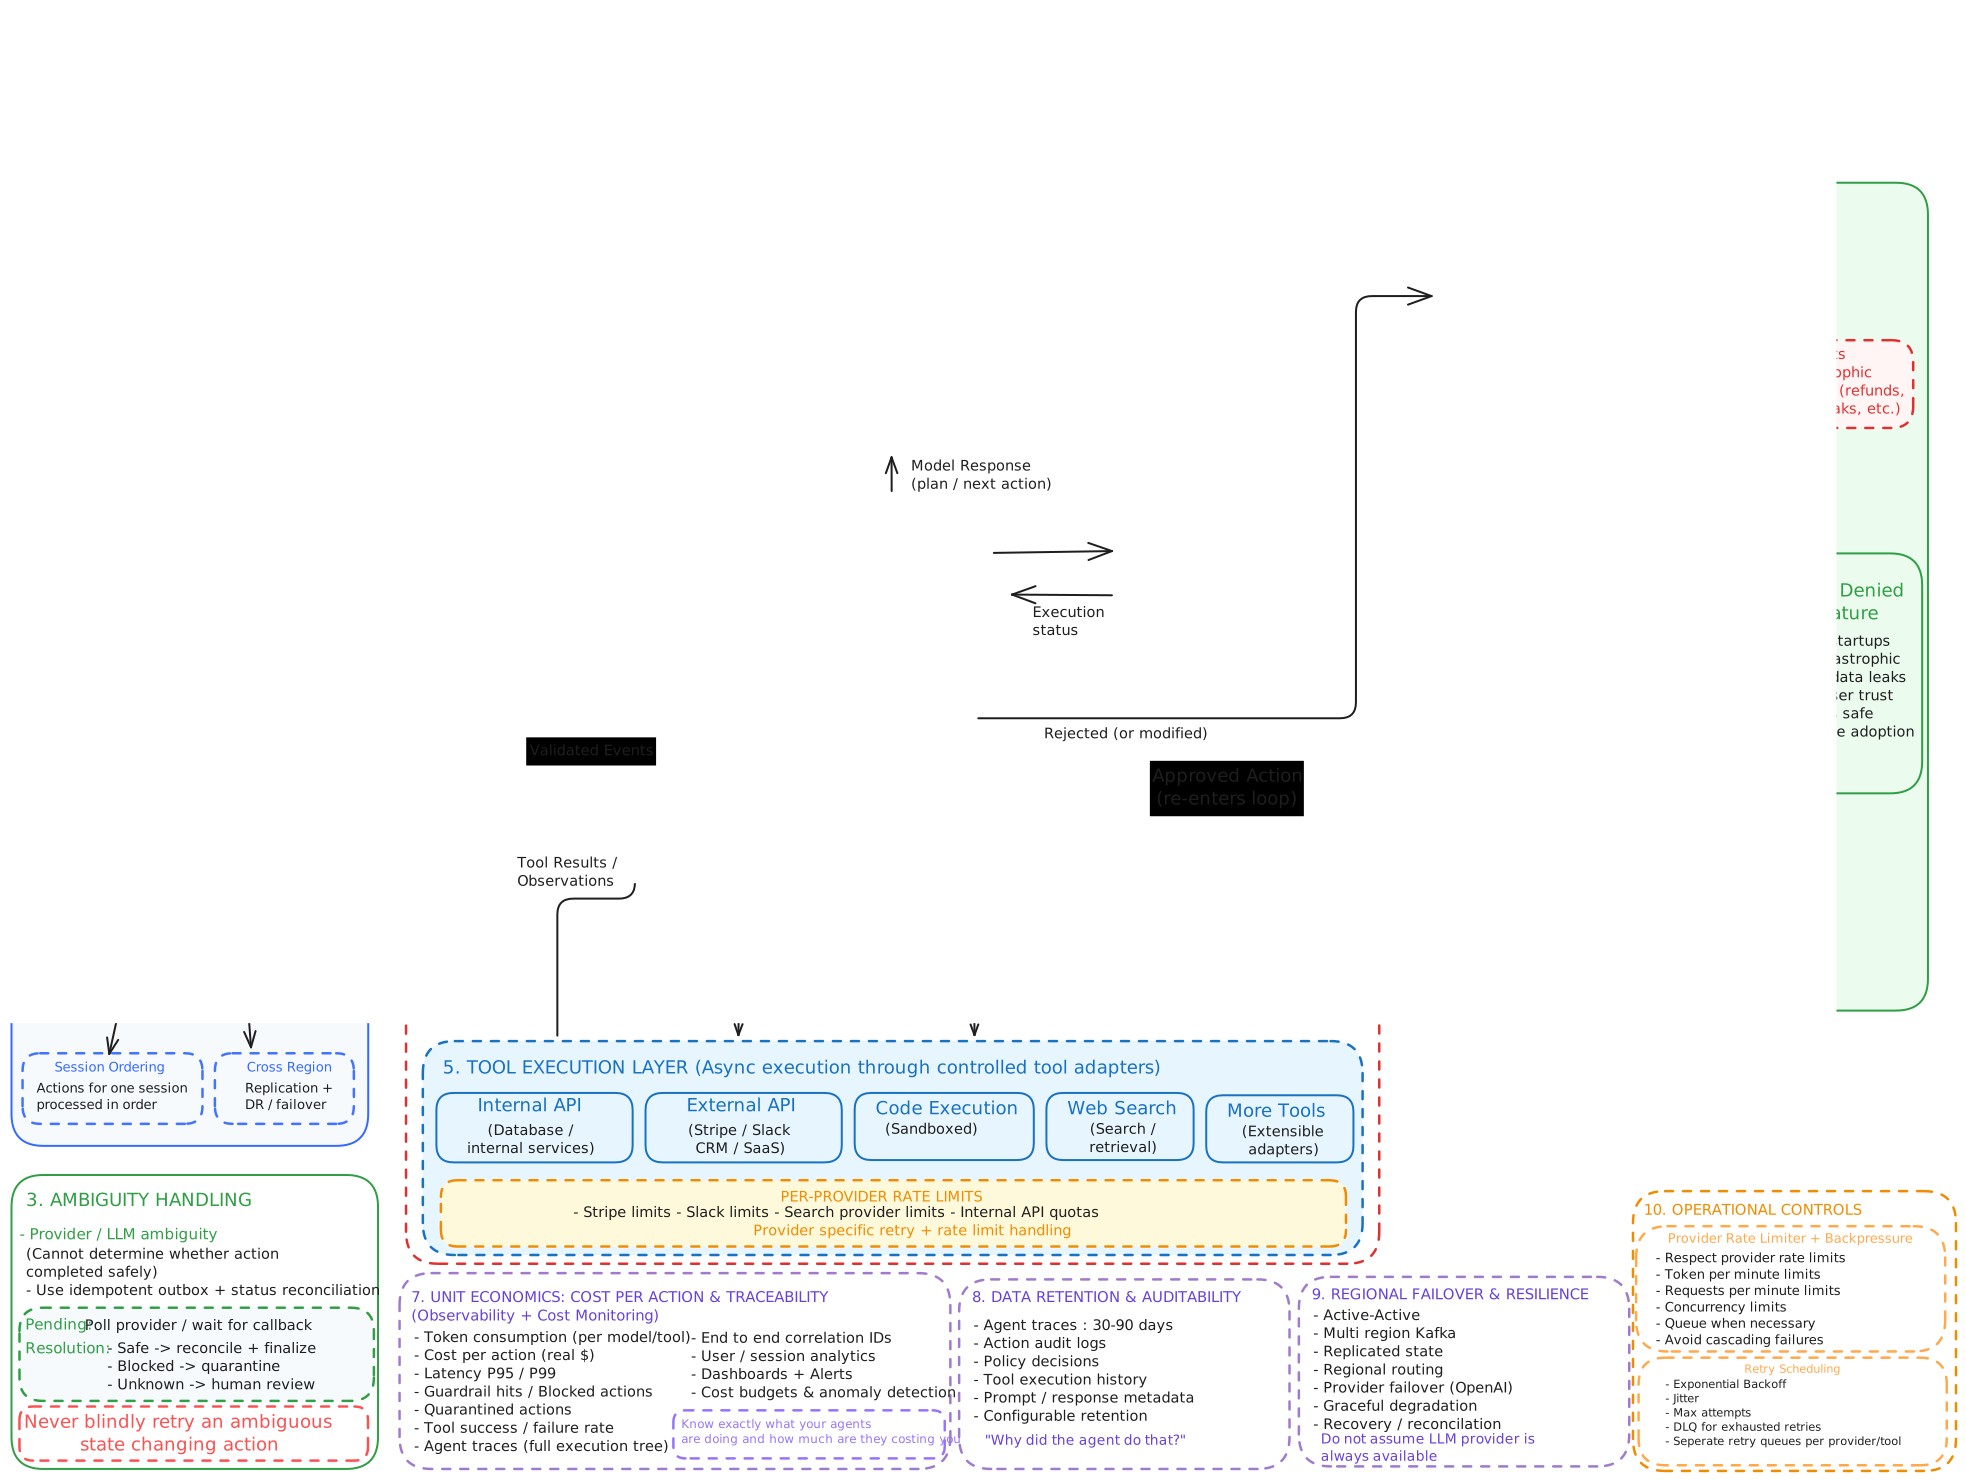
The problem
AI agents are easy to prototype, but incredibly difficult to run at scale. As you scale from 10 to 100,000 concurrent agent sessions, you face three massive bottlenecks: catastrophic failure loops (agents crashing on a single API timeout), runaway LLM costs, and the risk of agents executing unauthorized, state-changing actions on production databases.
The solution
A Large-Scale AI Agent Orchestration System built on event-driven architecture, strict risk-based routing, and multi-region resilience.
Core capabilities
Event-Driven & Async
Ingestion via multi-region Kafka, decoupling the agent runtime from the execution layer to ensure no LLM provider timeout can block the system.
Cost-Aware Model Routing
A dynamic router sends 80% of simple tasks to cheap models (Haiku/Llama), 15% to mid-tier models, and only 5% of complex tasks to expensive models (GPT-4o), cutting costs ~10x with minimal quality loss.
Guardrail-Enforced Safety
A Policy Engine splits actions into a Fast Lane (read-only, auto-execute) and a Slow Lane (writes and dangerous actions, requiring human approval).
Human-in-the-Loop Fallback
A Quarantine Store holds ambiguous or high-risk actions until a user explicitly approves them, preventing catastrophic refunds or data leaks.
Zero Unauthorized Writes
Idempotency stores and strict status reconciliation prevent duplicate actions and hold a 99.94% action validation SLO.
Why this matters
It provides the resilient, cost-controlled, and auditable infrastructure required to move AI agents from experimental demos to reliable, enterprise-grade production systems.
